Machine Learning in Financial Markets
Machine learning can classify regimes, rank opportunities and detect nonlinear patterns, but financial data is noisy and easy to overfit. Learn the full evidence pipeline from point-in-time features and temporal validation to drift monitoring.
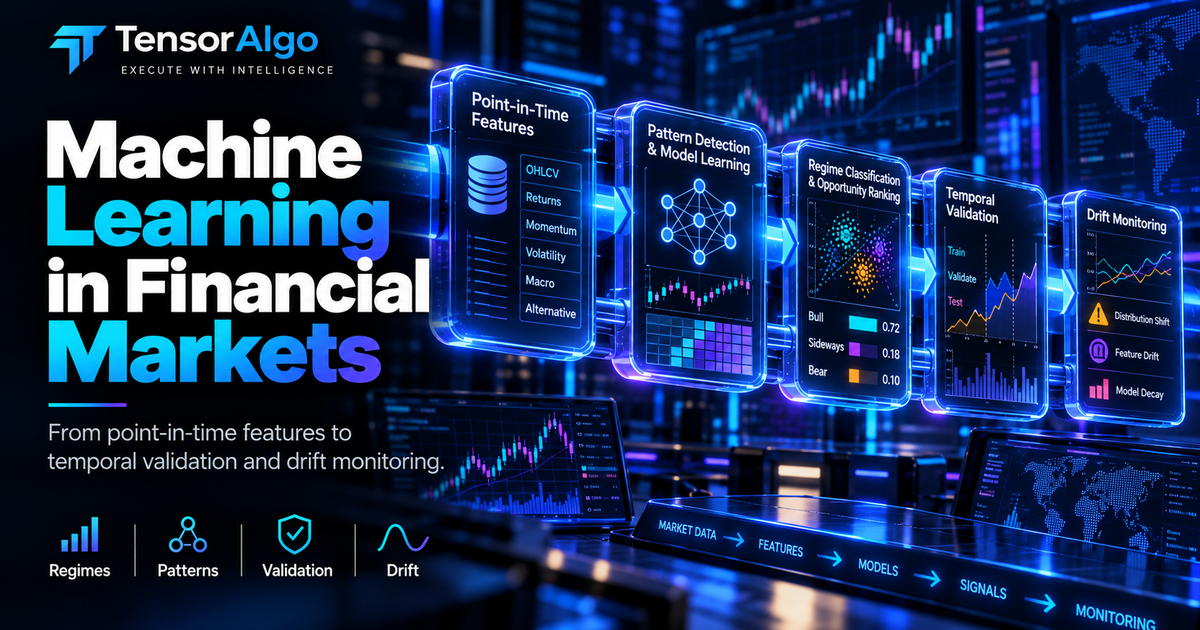
Machine Learning in Financial Markets: A Practical Guide to Building Evidence
Machine learning can identify nonlinear relationships, classify market states, rank opportunities, and detect anomalies. Financial time series, however, are noisy, adaptive, and unusually easy to overfit.
Educational information only. Model results and historical tests do not guarantee future trading performance.
Frame the problem before choosing a model
Start with a decision, not an algorithm. Examples include:
- classify trend versus balance;
- estimate transition risk;
- rank candidate setups;
- detect abnormal liquidity;
- estimate a bounded future outcome.
Define the timestamp at which the decision occurs and exactly which information exists then.
Features
Features may include price/returns, volatility, volume, order flow, session context, cross-market relationships, options-derived analytics, or strategy state.
Every feature needs a timestamp and provenance. If a feature is finalized only after the decision point, it cannot be used as though it were known earlier.
Labels
Labels encode what the model is asked to learn. A “winning trade” label can hide important questions: entry rules, horizon, stop/target logic, transaction costs, and overlapping observations.
Prefer labels tied to the actual decision the model will support.
Chronological splits
Randomly shuffling financial observations can leak temporal structure. Use time-aware training, validation, and test periods. Walk-forward evaluation repeatedly trains on the past and tests on a later unseen window.
Keep a final untouched test set where practical.
Leakage traps
Common leakage sources include:
- future bars in indicators;
- full-sample normalization;
- revised macro data;
- labels overlapping features;
- selecting features after inspecting test results;
- repeated tuning against the same “holdout.”
A sophisticated model cannot repair contaminated evaluation.
Class imbalance
Rare events such as large moves or specific setups can create imbalanced labels. Accuracy may then be misleading. Precision, recall, PR curves, class-specific costs, and confusion matrices can be more informative.
Calibration
Classification scores are not automatically probabilities. If decisions depend on probability thresholds, evaluate calibration on unseen data.
Calibration can also drift as market conditions change.
Cross-validation for time series
Standard k-fold cross-validation may violate chronology. Use expanding or rolling windows and consider purging/embargo techniques when labels overlap in time.
The goal is to prevent nearby observations from sharing information that would not be independently available in production.
Costs and execution
A model can predict direction correctly and still produce an unusable strategy. Convert predictions into an explicit execution policy, then model spread, commissions, slippage, latency, and missed fills.
Evaluate the end-to-end policy rather than only model metrics.
Baselines matter
Compare complex models against simple baselines: always predict the majority class, a basic linear model, a simple regime rule, or the existing strategy without ML.
If complexity does not improve unseen outcomes meaningfully, it may not be justified.
Hyperparameter tuning and overfitting
Every tuning attempt consumes information from the validation set. Large searches can overfit even when the test process looks formal.
Track experiments, limit degrees of freedom, and prefer stable parameter regions to isolated optima.
Regime and concept drift
Monitor whether input distributions, label frequencies, calibration, and strategy outcomes change. A drift alarm is a reason to investigate, not an automatic instruction to retrain.
Retraining should pass the same validation gates as a new model.
Model promotion
A robust lifecycle can be:
research → historical validation → shadow → limited influence → monitored production
Each transition should have explicit acceptance criteria, versioning, and rollback.
Explainability and attribution
Feature importance can help diagnose models but does not necessarily establish causality. Use attribution to understand model behavior, detect suspicious dependencies, and communicate limitations.
Supervised, Unsupervised and Reinforcement Learning
Supervised learning maps features to known labels or targets. Unsupervised learning looks for structure without a target, such as clustering regimes. Reinforcement learning optimizes sequential actions against a reward signal. Each introduces different validation problems; none automatically creates a tradable edge.
Define the Unit of Observation
Decide whether one sample represents a bar, event, setup, order-book snapshot or complete trade. Overlapping observations can be highly correlated. Treating them as independent can make confidence appear much stronger than it is.
Temporal Validation
Financial data has order. A typical workflow trains on an earlier interval, validates on a later interval and preserves a still-later test period. Rolling or expanding walk-forward windows can repeat this through time. Random shuffling is often inappropriate when it allows information from neighboring future observations to influence training.
Purging and Embargo
When labels span future horizons, adjacent training and validation samples can overlap. Purging removes observations whose label windows overlap the test period; an embargo leaves additional separation. These techniques are especially useful when many event labels share future price paths.
Metrics Must Match the Decision
Accuracy can be useless with imbalanced labels. A rare-event filter may need precision, recall, PR-AUC, calibration and explicit false-positive/false-negative costs. A ranking model may need rank correlation or top-k utility. Ultimately translate model output into the economic decision it supports.
Probability Calibration
If a model says 0.70, determine whether that number is actually calibrated as a probability. Reliability diagrams and calibration error can compare predicted probabilities with observed frequencies on unseen data. Calibration can drift even when ranking performance remains stable.
Feature Leakage Example
Suppose a daily feature is normalized using the mean and standard deviation of the entire dataset. The transformation has indirectly used future observations. Fit preprocessing parameters on the training window and apply them forward. Leakage often hides in preprocessing rather than in the model itself.
Baselines and Ablations
Compare against simple baselines and remove feature groups one at a time. If a complex model cannot beat a naive regime rule or linear model on unseen data after costs, complexity has not justified itself. Ablations can also reveal when an apparently important feature is redundant.
Research References
The scikit-learn time-series cross-validation documentation illustrates why time-ordered samples require different validation. Bailey and co-authors' Probability of Backtest Overfitting addresses selection bias from repeated strategy searches. These are methodological references, not evidence that any particular model is profitable.
Production Lifecycle
Use a model registry or equivalent record containing training window, feature schema, code/version, parameters and evaluation. Then progress through research, historical validation, shadow, limited influence and monitored production. Connect this lifecycle with AI in Trading and Forward Testing.
TensorAlgo and Model Research
TensorAlgo can organize user-defined Playbooks, supported market context and trade-review evidence around a repeatable process, but model research still needs its own point-in-time data, validation and promotion criteria. Treat machine-learning outputs as evidence to evaluate rather than a shortcut around backtesting and forward testing. See the Support Center for current product scope.
Target Construction
A target such as 'price higher in 15 minutes' differs from 'trade reaches target before stop.' Define the event that matters to the downstream decision. Labels should reflect execution logic where possible rather than optimizing an unrelated statistical target.
Feature Timing
Store an availability timestamp, not only an observation timestamp. Economic data can be revised; session statistics may finalize later; higher-timeframe bars are incomplete before close. A feature is usable only when it was actually available.
Normalization
Fit scalers, encoders and feature-selection steps on training data only, then apply them forward. Full-sample preprocessing is a common leakage path because future distribution information enters the training representation.
Imbalanced Events
If only 5% of observations are positive, 95% accuracy can be achieved by predicting negative every time. Use confusion matrices, precision, recall and decision-specific costs. Resampling techniques must remain inside training folds to avoid contamination.
Threshold Selection
A classifier score becomes a decision only after a threshold or ranking policy is chosen. Select that policy on validation data, then freeze it for test/forward evaluation. Report sensitivity around the threshold.
Economic Utility
Translate model errors into trading consequences. False positives may incur spread and stop losses; false negatives may represent missed opportunities. Optimize the decision objective carefully rather than assuming statistical accuracy equals economic value.
Feature Importance Caveats
Importance and SHAP-style attributions describe model dependence under assumptions; they do not prove causality. Use them to diagnose suspicious features, drift and redundancy rather than telling causal stories the experiment did not establish.
Drift Types
Covariate drift changes feature distributions; label drift changes outcome frequency; concept drift changes the relationship between features and target. Monitoring which layer changed helps decide whether the problem is data, regime or model.
Retraining Policy
Define when retraining is considered, what window it uses, how the candidate is validated and how it competes with the incumbent. Never replace production simply because a newer model exists.
Reproducibility
Record dataset snapshot, code commit, feature schema, random seeds where relevant, model parameters and metrics. A result that cannot be reproduced cannot be investigated reliably when production behavior differs.
Ensembling
Combining models can reduce variance, but correlated models often fail together. Evaluate incremental value and operational complexity. More models also create more versions, dependencies and monitoring requirements.
Related Guides
Connect research to Backtesting, then Forward Testing. For generative/tool-using systems, AI in Trading covers additional grounding and safety concerns.
Walk-Forward Example
Train on an initial historical window, tune on a following validation window and evaluate on the next unseen block. Advance the windows and repeat. Keep each unseen result before making the next change. This approximates the sequence in which a production model would encounter new data.
Leakage Audit
For every feature, ask when its raw inputs arrive, when the transformation is calculated and whether any full-sample statistic is used. For every label, ask how far into the future it looks. Then inspect whether training samples overlap validation label horizons.
Model Selection
Prefer the simplest model that delivers stable unseen utility. More expressive models can capture real nonlinear structure but also increase degrees of freedom. Compare complexity against baselines under identical splits and costs.
Uncertainty
Point predictions hide distributional uncertainty. Depending on the task, prediction intervals, calibrated probabilities or ensembles can communicate uncertainty, but each requires validation. Do not turn uncertainty estimates into certainty through interface wording.
Production Monitoring
Log feature availability, score distribution, decisions, outcomes and model version. Alert on missing features, distribution shifts and unexpected score concentration. Performance monitoring without input monitoring can detect problems too late.
Research-to-Production Checklist
Freeze feature schema, target, preprocessing, model, threshold and risk policy; reproduce the evaluation; run shadow; compare with baseline; test failure modes; define rollback; then promote. This sequence is slower than deploying a promising notebook and far safer.
Time Is Part of the Model
Financial observations are ordered. Randomly shuffling them can allow the training process to learn from a distribution that includes information unavailable at the decision date. Use chronological splits and, where necessary, a gap or embargo between training and evaluation windows when labels or features overlap through time.
Scikit-learn's documentation demonstrates time-sensitive cross-validation with TimeSeriesSplit and explicit gaps. A production trading study may need stricter controls, but the principle is the same: the evaluation set must represent information that arrives after the data used for fitting and selection.
The Backtesting Guide covers the broader experimental design, while Forward Testing explains how the frozen candidate should meet live-arriving data.
Define the Target Before the Features
A target such as “price is higher in 20 bars” can be mathematically valid yet economically useless after costs. Define the decision the model is meant to support, horizon, label timing and how predictions translate into actions before feature engineering begins.
Then audit every feature for availability. Session statistics, rolling indicators, fundamentals and alternative data must be computed only from information known at the prediction timestamp. Point-in-time correctness matters more than a large feature count.
Baselines and Calibration
Compare complex models with simple baselines: persistence, unconditional frequency, a small linear/logistic model, or the existing rule-based process. If the complex model does not add stable out-of-sample value, complexity is not justified.
For probabilistic classifiers, inspect calibration rather than only accuracy. A model that says “70%” should be evaluated on whether comparable predictions actually occur near that frequency over appropriate samples. Thresholds should then be selected based on decision utility and costs, not a generic 0.5 cutoff.
The What Makes a Trading Strategy Profitable? guide connects model outputs to net expectancy rather than headline classification metrics.
Drift Is a Production Problem
Monitor feature distributions, prediction distributions, calibration, realized outcomes, missing-data rates and latency. A sudden change can mean market regime shift, upstream data failure or code regression. Retraining automatically on every drift alert can amplify a data problem; diagnose first.
The AI in Trading guide covers governance for models that also generate or summarize information, while Trading Automation Explained covers production state and failure recovery.
Research Discipline
Bailey and coauthors' Probability of Backtest Overfitting is relevant because machine learning expands the number of configurations researchers can try. Record experiments, preserve unseen data, report the search budget and prefer stable regions of performance over a single best parameter set.
Machine learning is most useful when it turns a bounded prediction or classification problem into measurable incremental evidence. It is least trustworthy when model complexity hides weak data provenance or an uncontrolled research process.
Reproducibility Checklist
For every experiment, preserve the data snapshot or query logic, feature code, target definition, split dates, preprocessing, model parameters, random seed where applicable, evaluation metrics and the exact decision threshold. Without these, a promising result can be impossible to reproduce or audit.
Also record failed experiments. Model research has the same multiple-testing problem as strategy research: if only the winning configuration survives in the notebook, later reviewers cannot judge how much searching preceded it.
A production candidate should therefore arrive with more than a serialized model. It should include the evidence trail that explains what data created it, what tests it passed, what conditions it has not seen and what monitoring would indicate that its assumptions are degrading.
Frequently Asked Questions
What can machine learning do in financial markets?
Depending on the problem, it can classify regimes, rank opportunities, estimate conditional outcomes, detect anomalies or model nonlinear relationships in market data.
How do you prevent data leakage in market models?
Use point-in-time features, chronological validation, decision-time timestamps and pipelines that prevent future information from entering training or evaluation.
Does higher prediction accuracy mean a better trading strategy?
Not necessarily. Economic value depends on calibration, costs, payoff, trade frequency, false positives and how predictions change actual decisions.
When should a model be retrained?
Retraining should respond to defined evidence such as drift or degradation and still pass validation. A newer model is not automatically a better model.
Final Takeaway
A financial model earns trust through the full evidence pipeline: point-in-time data, a well-defined target, temporal validation, realistic costs, calibration, forward monitoring and controlled promotion. Model complexity is useful only when that chain improves.